Showing posts with label aho-corasick. Show all posts
Friday, 6 May 2011
On the bioinformatics or: computer science's pillars
One of the most interesting facets of bioinformatics is that pushes computer science towards its limit. When you deal with huge data sets, a poorly implemented algorithm or the choice of the wrong data structure leads to inevitable failure.
Screenshot above shows some information about the costs of a piece of software I'm developing for prof. Besozzi, that executes a slight variation of Aho-Corasick on saccharomyces cerevisiae's genome, looking for a bunch of relevant nucleotides sequences. The data-set isn't impressive, just 36MB, and loading it into main memory takes about 10MB. The remaining 128 megabytes are due to the tables produced by algorithm and the huge vectors that store the results (>7 million of matches).
This being the ratio, one can easily foresee that bigger data sets (eg.: the human genome) could easily get out of hand, requiring more resources than one can afford! I'm more than satisfied in terms of time complexity (it's a linear algorithm, therefore optimal), but some further optimization could (has) to be done on the spatial side.
Tuesday, 8 February 2011
Realizzi di esser stato d'aiuto quando...
...trovi il tuo blog linkato nelle dispense di due università americane (Central Florida e Central Connecticut). Nice!
Il mio post sul workaround per far funzionare Dev-CPP sotto Vista (dio maledica Microsoft per le sue trovate balzane) è diventato un po' il fix de facto in giro per internet, e ha portato più traffico e commenti delle altre centinaia di post che ho realizzato, anche quelle probabilmente più utili come l'implementazione di Aho-Corasick in PHP (la prima open-source, afaik).
Quest'ultima è un fenomeno interessante, in quanto mi ha provocato solamente un'ondata di spam pornografico nei commenti... in giapponese. Qualcuno deve aver linkato il post su un sito del sol levante (che non riesco a recuperare), e da lì è partito un assalto che, dopo quasi un anno, non accenna ad arrestarsi.
Il mio post sul workaround per far funzionare Dev-CPP sotto Vista (dio maledica Microsoft per le sue trovate balzane) è diventato un po' il fix de facto in giro per internet, e ha portato più traffico e commenti delle altre centinaia di post che ho realizzato, anche quelle probabilmente più utili come l'implementazione di Aho-Corasick in PHP (la prima open-source, afaik).
Quest'ultima è un fenomeno interessante, in quanto mi ha provocato solamente un'ondata di spam pornografico nei commenti... in giapponese. Qualcuno deve aver linkato il post su un sito del sol levante (che non riesco a recuperare), e da lì è partito un assalto che, dopo quasi un anno, non accenna ad arrestarsi.
Tags:
aho-corasick,
dev-cpp,
eecs,
php,
spam,
ucf,
university,
workaround,
www
Monday, 28 June 2010
Aho-Corasick (multiple pattern match) in PHP
When I started programming Mergifier, my "RSS feeds dispenser", I knew I was going to need some kind of terms filtering. It's useless to take into account the most common words, for they don't bring any information.
My initial solution was to split the text into an array of substrings and use array_diff to remove those in my blacklist array. I don't know the asymptotic cost of array_diff algorythm, but using it with plenty of items (featuring long titles, summaries and descriptions) soon appeared a bit too expensive.
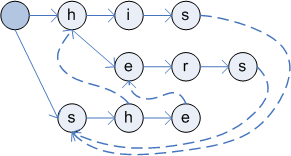
Recently I studied a lot of pattern matching algorythms, including the well known "Aho-Corasick" which checks occourrences of multiple patterns "at once" inside a text of length n in O(M+n), being M the total number of characters composing the patterns. Useful for virus signature detection and bioinformatics, I did not find its implementation anywhere, so I did my own!
Download the code
As you could see inside the code, this algorythm is cool because one can precalculate delta/phi transition tables and cache them, brutally speeding up computations on many different texts made of many terms.
If you find this code useful, or if you have any kind of suggestion to improve it, please let me know. :)
My initial solution was to split the text into an array of substrings and use array_diff to remove those in my blacklist array. I don't know the asymptotic cost of array_diff algorythm, but using it with plenty of items (featuring long titles, summaries and descriptions) soon appeared a bit too expensive.
Recently I studied a lot of pattern matching algorythms, including the well known "Aho-Corasick" which checks occourrences of multiple patterns "at once" inside a text of length n in O(M+n), being M the total number of characters composing the patterns. Useful for virus signature detection and bioinformatics, I did not find its implementation anywhere, so I did my own!
Download the code
As you could see inside the code, this algorythm is cool because one can precalculate delta/phi transition tables and cache them, brutally speeding up computations on many different texts made of many terms.
If you find this code useful, or if you have any kind of suggestion to improve it, please let me know. :)
Subscribe to:
Posts (Atom)